Give your agent a secure filesystem and a work environment
 Rafael
Computerwelt, part 4 of 4. Part 1 was the port, part 2 the library, part 3 the assistant we built on it. This post is the same shape, opened up.
Sudo's shell is written in our code, against the workspace configuration. The interesting question is what happens when a developer in a workspace wants the same arrangement over their data: a fleet of vehicles, a document corpus, a ticket queue, a set of contracts.
The answer is that an AI tool can return an ISandbox instead of exposing [Tool] methods.
Everything else about it is the ordinary AI tool machinery: the same editor, the same access
modes, the same versioning, the same tool picker, the same definitions export. The only
difference is that calling it does not invoke a method of your class. It runs a bash script
against a filesystem your code built.
public class FleetSandbox : ISandbox
{
    // Read by the model when it decides whether to call this. The mount list is
    // appended automatically — do not repeat it here.
    public string Description => "Every vehicle in the fleet, as files.";

    // What the model calls it. Two sandboxes both called `sandbox` in one chat
    // would be ambiguous, so name yours.
    public string FunctionName => "fleet";

    public SandboxMount[] Mounts => new[]
    {
        SandboxMount.Live("/vehicles", "one .json per vehicle", ReadVehicles),
        SandboxMount.Scratch("/work", "scratch space"),
    };
}

return new FleetSandbox();
That is a complete sandbox. Description and Mounts are the only members without a
default.
Why this instead of more tools
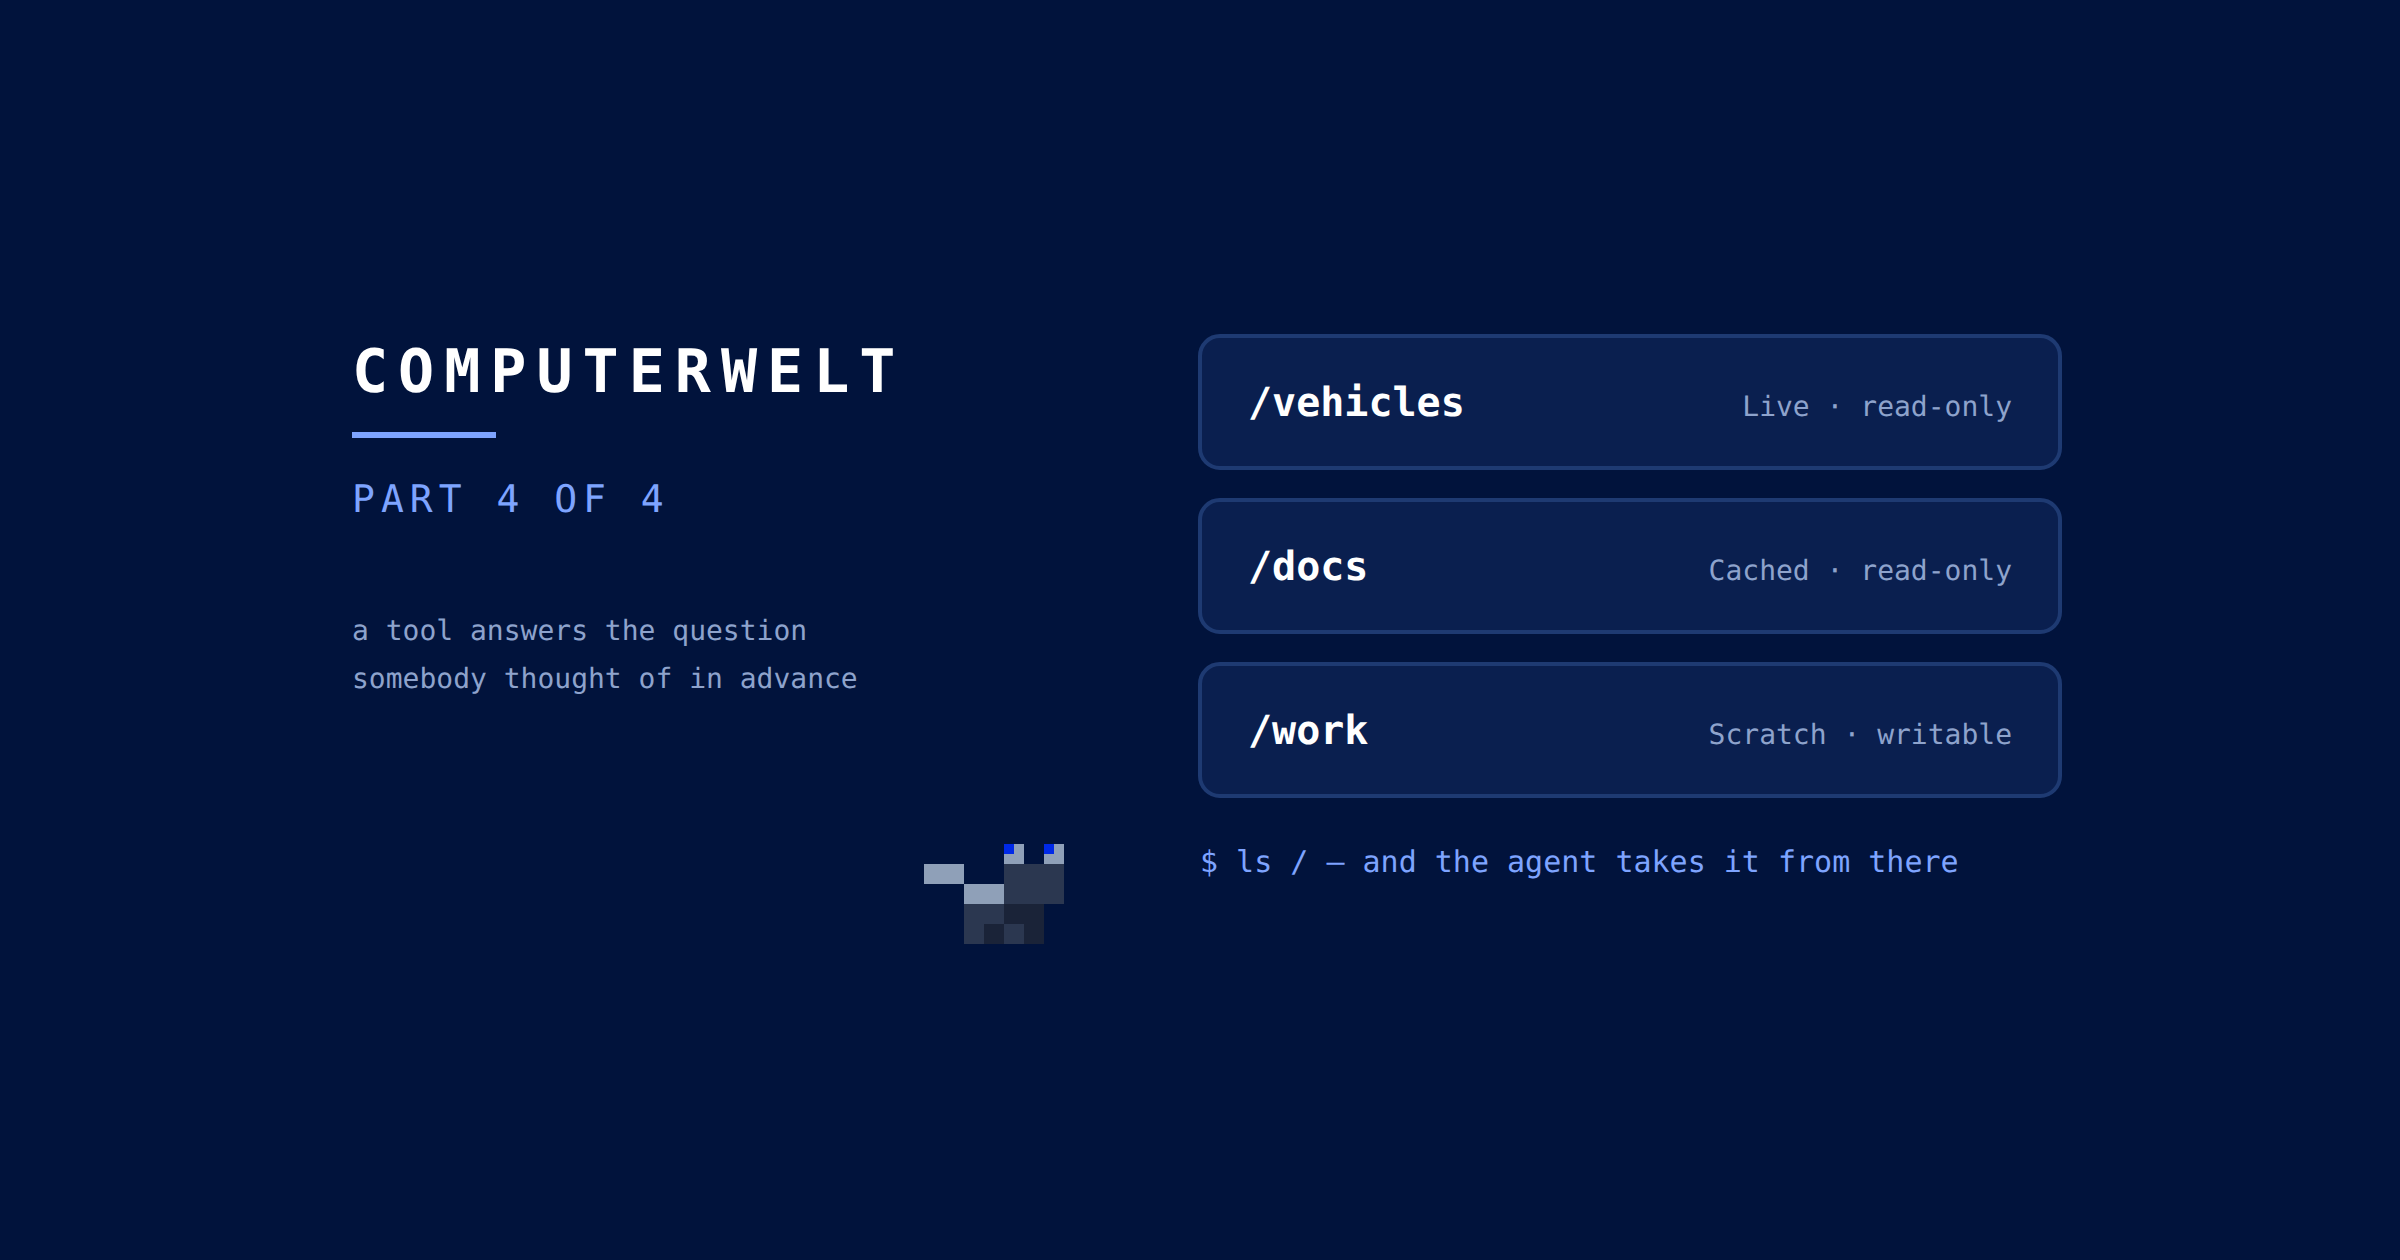
A tool answers the question somebody thought of in advance, and grows a method per question. That is the right shape when the surface is a handful of fixed calls ("book this slot", "start that job"), and it is the wrong shape when the useful questions are open-ended.
A sandbox hands the model ls, grep, rg, sed, awk, jq, yq, sort, uniq,
comm, diff and python over the data, and lets it answer one nobody wrote down. It is
the same move part 3 describes, where seventy-four tools
became one shell — except here it is available to whoever is building the assistant, not
only to us.
The practical consequence is that the most common mistake when writing one is adding a command for something the shell already does. Roughly a hundred and twenty commands are already there:
| Family | Commands |
|---|---|
| Read and slice text | cat head tail wc cut paste column comm sort uniq tr rev tac nl shuf |
| Search and edit | grep, rg, sed, awk, diff, xargs, tee |
| Structured data | jq for JSON, yq for YAML |
| Walk the tree | ls tree find stat file du df realpath basename dirname |
| Change files | mkdir rm cp mv ln touch chmod truncate mktemp |
| Inspect bytes | od xxd strings numfmt md5sum sha1sum sha256sum |
| Shell proper | pipes, redirection, $(...), globs, if/for/while/case, functions, arrays, heredocs, trap, test, seq, expr, bc, timeout |
And python, over the same filesystem, so a script can write a file and a Python program
three lines later can read it.
The mounts are the interface
A mount is a flat list of files. The directories between them are synthesised from the
names, so a reader that yields people/ada.json is walkable with ls, find, tree and
grep -r with no tree to build. It is the same rule the definitions export is served
under, and a rule for the same reason: one list is the source of truth.
What produces that list is your code, handed the tool scope of the script that is running: the graph as the user who is chatting, the current chat, the logger, the HTTP client factory. Which factory you use decides when it runs, and whether the sandbox may write over it:
| Factory | Your reader runs | Writable |
|---|---|---|
SandboxMount.Cached(path, description, read) |
once per session | no |
SandboxMount.Live(path, description, read) |
before every script | no |
SandboxMount.Writable(path, description, read) |
before every script, plus what the session wrote | yes |
SandboxMount.Scratch(path, description) |
never — it starts empty | yes |
SandboxMount.Files(path, description, files) |
once, from a set you already have | no |
SandboxMount.Lazy(path, description, listDirectory, readFile) |
per directory, and per file, as the agent walks in | no |
Live is the right default for anything read out of the graph: a second call should see
what changed in between. Cached is for something expensive that does not move.
Names are eager, content is lazy
This is the one performance fact worth internalising, and it is the one that bites.
SandboxFile.Lazy(path, () => text) defers the file's content until something actually
reads it, and remembers it for as long as that listing lives. Nothing defers the names:
your reader returns the whole list of paths for the mount, every time it runs. So on a
Live mount, a reader that walks 50,000 nodes to name 50,000 files walks them again for
pwd, for ls /work, and for every command the agent types.
When a set is too large to enumerate, SandboxMount.Lazy names nothing until something
asks:
SandboxMount.Lazy("/data", "one folder per node type, one file per record",
    listDirectory: (scope, directory) => directory.Length == 0
        ? Task.FromResult(SandboxDirectory.Of(Types.Select(SandboxEntry.Directory)))
        : Task.FromResult(SandboxDirectory.Of(KeysOf(scope, directory).Select(k => SandboxEntry.File(k + ".json")))),

    readFile: (scope, path) => Task.FromResult(SandboxFile.Text(path, Render(scope, path))));
ls, find, tree, grep -r and globs all walk one directory at a time, so each of them
costs what it touches. ls /data asks for the type list and reads nothing;
cat /data/people/ada.json produces exactly that one record. Listing never reads a file:
ls is answered from the entries you returned, which is why SandboxEntry.File takes an
optional size.
A lazy mount is not always the answer, though. Three cheaper moves, when they fit:
- Publish an index, not a file per row. One
records.jsonlan agent cangrepandjqbeats 50,000 files it has tofind, and it is far friendlier to the glob cap. - Cap, and say so. Cut an eager listing at a size that stays useful and put the cut in
a
README.md, so the agent does not report a prefix as the whole. - Give the long tail a command.
lookup <key>that queries on demand is exact where a cap is not, and costs nothing until it is called.
A write reaches the session, and nothing else
This is the containment rule, and it is the one that decides how a sandbox is designed.
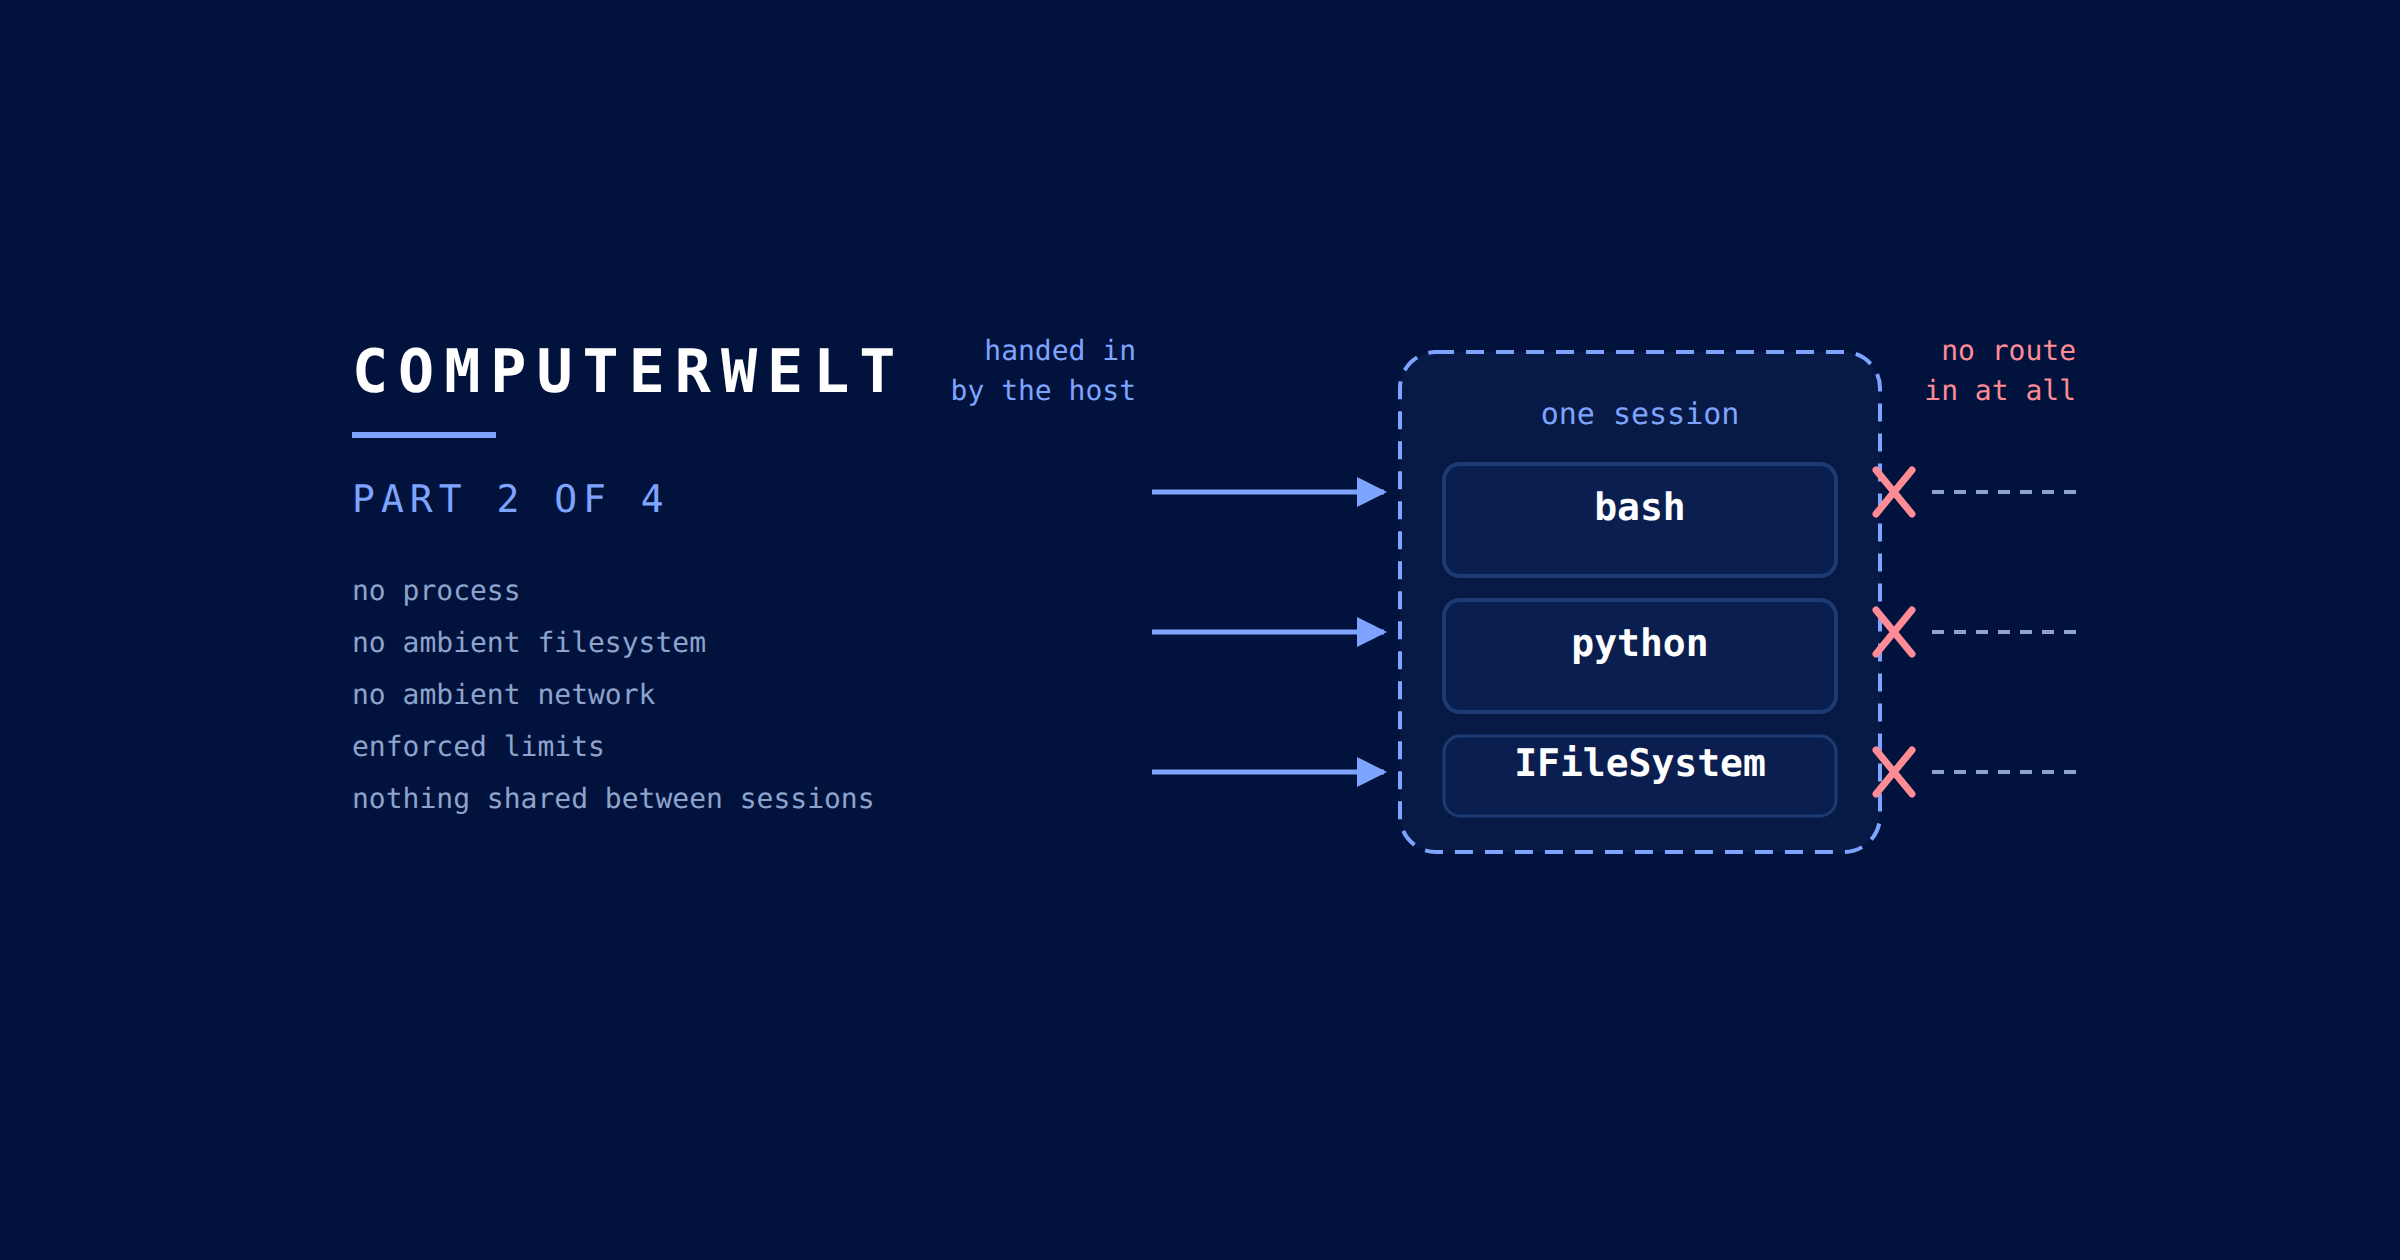
Writes land in the session's overlay and are persisted with the conversation. They reach no
other conversation and nothing in the workspace. So if a sandbox should be able to act on
something, that is not a write; it is a command whose name says what it does. Which is the
same split as Sudo's, where editing a file is free and commit is the thing an admin has to
approve.
public SandboxCommand[] Commands => new[]
{
    SandboxCommand.Create(
        "vehicle",
        "vehicle <registration>: the full record for one vehicle, including history. "
      + "Use this instead of reading /vehicles when you know the registration.",
        async call =>
        {
            if (call.Arguments.Count == 0) return call.Fail("usage: vehicle <registration>");

            return await Fleet.DescribeAsync(call.Scope, call.Arguments[0]);
        }),
};
A command is for what a file cannot be: an action with an effect, a lookup whose argument space is too large to enumerate as files, a computation that belongs on the server.
call carries the script's Scope, its Arguments, its StdinText (so the command can
sit in a pipe), its Files, and a CancellationToken that is cancelled when the script runs
out of wall clock or the turn is stopped. call.Fail(...) ends it with the message on stderr
and a non-zero exit code, so a script chaining with && stops there. Returning that rather
than throwing is the difference between "you called it wrong" and "something broke": an
exception out of a command is reported as one.
Usage is the only documentation the model gets. It is worth writing as a manual page entry
(argument shape, what it does, when to reach for it instead of reading a file) rather than as
a label. And a name the shell already answers to is refused at validation rather than
shadowing the real command.
The filesystem is the state
call.Files is the sandbox's own filesystem as the script sees it: ReadTextAsync,
WriteTextAsync, ExistsAsync, ListAsync, RemoveAsync, ResolvePath. A relative path
resolves against the directory the script is in now, so mycmd out.txt after a cd means
what it looks like. A write to a read-only mount is refused exactly as echo > file would
be. The mount kinds keep deciding what may change, and a command is not a way around them.
That is what makes a stateful command possible with no state of your own. A writable mount is
remembered with the conversation, so a todo command that keeps its list in /work/todo.md
survives the turn, the agent can cat the file without the command, and nothing else in the
sandbox had to learn about it.
When the answer is a document
A sandbox answers questions. When the answer is a deliverable (a report somebody will send on, a page with a chart in it), one line says so:
public ArtifactType[] Artifacts => new[] { ArtifactType.Html, ArtifactType.Pdf };
That adds an /artifacts mount and a publish command. The agent writes report.md or
page.html there, publishes it, and the chat shows it beside that tool call as something
the reader opens in the pane next to the conversation. Writing shows nobody anything;
publishing is what does. So an agent that revised a document four times leaves one chip,
not four. The source stays in the mount, so a later turn reads it back and revises it.
An HTML artifact renders in a frame that can reach nothing at all: no CDN, no font, no
fetch.
What is checked, and what is clamped
Compiling proves the code builds. It does not prove the filesystem resolves, so a second pass does: a mount path that is not one absolute segment, a duplicate mount, a command shadowing a command the shell already has, a home directory under no mount. Each is refused with its reason, and the admin listing reports it per sandbox, so it is not first met by an agent calling one.
The budget is the sandbox's to ask for and the workspace's to bound:
| Default | Ceiling | |
|---|---|---|
MaxDurationSeconds |
60 | 300 |
MaxOutputBytes |
256 KB | 4 MB |
MaxOutputBytes is a context budget as much as a resource limit: what the script prints is
what the model reads. A sandbox's own numbers are clamped to the ceilings, so a workspace can
never be handed a script with no budget by a tool that asked for one.
Sessions are per chat and per tool, so two sandboxes open in one conversation are two
working directories and two sets of files. A session is held in memory for 30 idle minutes
and written back after any script that changed something; a session that only read leaves
nothing behind. Editing the tool recompiles it into a new ISandbox, and the registry drops
the session built from the old one rather than serving a filesystem its author has already
replaced.
Designing the layout
The mounts are the whole interface. An agent that can list a directory needs no catalogue of tools to discover what is there, which means the layout is the API design, and deciding it before writing a reader is what keeps a sandbox from being one undifferentiated folder.
| Role | Holds | Usually |
|---|---|---|
| the subject matter | the records the agent came for | Live, read-only |
| worked examples | one filled-in example of each shape it will meet | Cached |
| documentation | what the fields mean, what the codes stand for, what is not in here | Cached |
| live state | counts, queue depth, the last run — regenerated on every read | Live |
| scratch | somewhere to put a working file | Scratch |
Two rules are worth following whatever the layout.
A generated file that is also the record has two sources of truth. When a mount renders
something the sandbox can also be asked to change, keep the mount read-only and let a command
be the only writer. Otherwise a sed behind that command's back leaves two answers and no
way to tell which is current.
A file that cannot be produced says so in its own content, rather than being absent or
empty. Absent reads as "there is none of that", which is a different answer and a wrong one.
A mount whose reader throws becomes an _ERROR.txt holding the message for exactly that
reason: an agent can read that and report it.
That is the series. The interpreter is MIT-licensed on GitHub, and so are the two Rust projects it is a port of: bashkit and monty. Thanks to both.
Read next
Articles on context graphs, enterprise search and industrial AI