Optimising code with agents on a machine that won't hold still
 Rafael
Coding agents are unusually good at optimisation. It is pattern work over a bounded surface: hoist the allocation, block the loop, give the reduction its own accumulators, stop rebuilding the offsets. An agent will happily do forty of those in an afternoon.
The problem is that it cannot tell which ones worked.
Most of our performance work now happens on cloud-hosted agents: Claude Code sessions running in a container somewhere, with no human watching the terminal. That container is not a lab bench. Between one shell invocation and the next it can be rescheduled onto a different CPU with a different vector width. It shares a physical host with other tenants who are also busy. Its core count is whatever the hypervisor feels like offering. We have watched the same unchanged benchmark, run twice in one session, differ by 40%.
An agent measuring in that environment, with no discipline imposed on it, will confidently report wins that are scheduling noise and revert real improvements that happened to land during a noisy minute. Both failure modes have happened to us, and both are expensive: the first leaves dead code in the tree with a comment claiming it is faster, the second throws away work and, worse, records a wrong conclusion that the next agent reads as fact.
So the interesting question is not can an agent optimise code. It is what measurement discipline makes an agent's optimisation verdicts trustworthy on hardware that will not hold still. This post is the four rules we settled on, the code that implements them, and what they found in four real ports.
What goes wrong, concretely
Before the rules, the failures they exist to prevent. All of these are from our own repositories.
The first configuration measured pays for the page cache the others inherit. While porting PaddleOCR-VL to C#, an agent tested whether turning off background GC helped a stage that churns 4.5 GiB of large tensors. Five warm runs with it on: 8.3–9.0 s. Five with it off: 5.6–6.1 s. A clean, large separation, and completely false. The configurations had run in sequence, and the whole sequence drifts downward as 125 MB of model weights settle into the page cache. Interleaved on-off-on-off, the medians are 5.12, 5.27, 5.19, 5.32 s. No effect at all.
A stage bound by something other than its kernel reports every kernel change as neutral. The same port tried transposing the vision tower's attention keys so the score product would stop reducing along the vector lanes. Measured 7,955 ms against a 7,948 ms control, and was reverted as a dead end. It was re-measured months later and kept: it is worth about 20% of that stage. The first measurement was correct. The conclusion drawn from it was not. At the time, the stage was running six or seven pool threads on four cores, so it was contention-bound and no kernel change could have shown through.
Cold processes never reach the code you benchmarked. A CLI tool parses one document and exits. Nothing in it ever reaches the steady state tiered compilation is designed for, so the first pass through a model graph runs as tier-0 code. Compiling optimised up front took a page from 10.7 s to 8.1 s without touching a single kernel.
And microbenchmarks lie in at least three specific ways, each of which reports roughly a fifth of the truth while looking entirely reasonable. More on those below, because they are what ruins the calibration step that everything else depends on.
Rule 1: measure the machine before you measure the code
A stage time in milliseconds is not comparable across runs on a shared host. So every benchmark run in the PaddleOCR port starts by measuring the machine itself, before anything is loaded: the FMA rate the hardware will actually sustain at each vector width, at one thread and at every thread, and the read bandwidth at each level of the cache hierarchy. Stage times are then reported as a fraction of those ceilings as well as in milliseconds, and that fraction is the figure that still means something tomorrow.
The output heads every run, in this shape:
Machine (measured before loading anything)
  4 threads, 512-bit vectors (runtime prefers 256), 2 FMA ports, ~2.94 GHz
  FMA          <256-bit>  <512-bit>  <all threads, and the scaling factor>
  Read       L1 <..>  L2 <..>  L3 <..>  DRAM <single> / <all threads>  (GB/s)
  Jitter     <spread across samples>
On our reference machine (four cores at about 3 GHz) that comes out at roughly 285 GFLOP/s all-thread, with L2 and L3 reads around 51 and 22 GB/s. Every one of those numbers moves between runs, which is the entire point of taking them.
Three of those lines do work beyond the obvious. The runtime prefers 256 note is why we
found that the tower's attention had no AVX-512 path while the GEMM beside it did. The ISA is
present but Vector512.IsHardwareAccelerated is false by default, so the two kernels had
silently diverged. The FMA ports count is inferred from the ratio between the two widths (a
core with one 512-bit unit doubles its FLOP rate when the vector doubles; a core with two gains
nothing), which is how the profile estimates the clock at all. And jitter is the honest error
bar on everything else: above a few percent the machine is busy with something and every stage
time in the run should be read as an upper bound. The profile says so in words, so an agent
reading its own output has a chance of noticing.
The measurement itself is short and mostly unremarkable, except where it isn't:
[MethodImpl(MethodImplOptions.NoInlining)]
private static double Fma256(int iterations)
{
    Vector256<float> x = Vector256.Create(1.0000001f);
    Vector256<float> y = Vector256.Create(0.9999999f);
    Vector256<float> a0 = Vector256.Create(1f), a1 = Vector256.Create(2f);
    Vector256<float> a2 = Vector256.Create(3f), a3 = Vector256.Create(4f);
    Vector256<float> a4 = Vector256.Create(5f), a5 = Vector256.Create(6f);
    Vector256<float> a6 = Vector256.Create(7f), a7 = Vector256.Create(8f);

    var clock = Stopwatch.StartNew();
    for (int i = 0; i < iterations; i++)
    {
        a0 = Vector256.FusedMultiplyAdd(x, y, a0);
        a1 = Vector256.FusedMultiplyAdd(x, y, a1);
        // ... six more independent chains
    }

    double seconds = clock.Elapsed.TotalSeconds;
    Consume(Vector256.Sum(a0 + a1 + a2 + a3 + a4 + a5 + a6 + a7));
    return seconds > 0 ? (double)iterations * ChainCount * 8 * 2 / seconds / 1e9 : 0;
}

/// <summary>Keeps a result alive without letting the JIT see a reason to spill.</summary>
private static void Consume(float value) => GC.KeepAlive(value);
None of that is incidental, and each detail was learned by getting it wrong:
- Eight chains, and they must be eight named locals. The JIT will not enregister an indexed
accumulator, an array or a
stackallocspan, so the indexed form measures store-to-load forwarding and reports about a quarter of the machine's real rate. - The accumulators are seeded with different values. Started at zero they would all hold the
same number after every step, the JIT proves the chains equal and emits one
vfmadd231psreusing a single register. The loop then measures the FMA's four-cycle latency rather than its two-per-cycle throughput, and reports about a fifth of the truth. - The result is consumed with
GC.KeepAlive, not avolatilefield. A volatile store is a release barrier, and the JIT responds by keeping every SIMD local in the frame across the loop. The body becomes load-operate-store and reports store-forwarding throughput. On our benchmark machine that one mistake turned 159 GFLOP/s into 27.
A calibration that is wrong by 5x is worse than no calibration, because every kernel measured against it then appears to be exceeding the hardware. Which, usefully, is a thing the code checks for and says out loud.
Rule 2: make sure you are measuring compiled code
Two separate problems hide under "warm up first".
The one everybody knows is JIT tiering: a .NET method starts at tier 0 and is only recompiled with optimisations after it has been called enough times. So every benchmark takes untimed passes first. The X-Ray.Content extraction benchmark opens with exactly that note, because it is comparing against a Rust binary that has no such warm-up phase and an unfair comparison would have been easy to publish:
The measurement discipline that matters here is warm-up. A cold .NET process spends its first passes in the interpreter and the quick JIT tier, and the extractor graph is large enough that tiered promotion takes a while to settle. Timing that measures the compiler, not the code.
The subtler one is on-stack replacement, and it bites precisely the loops you most want to
measure. A method entered once and then spinning for a billion iterations is escaped through OSR,
and OSR code keeps the frame's locals where tier 0 put them: on the stack. The loop head then
reloads all eight accumulators from memory and spills them again every iteration. Same
store-forwarding trap as above, arriving through a completely different door, and the fix is
[MethodImpl(MethodImplOptions.AggressiveOptimization)] on the benchmark body.
And then there is the case where the production answer is not to warm up at all. Our OCR CLI is a cold process every time. It parses a document and exits, so tiering never pays off, and we turned it off for the tool alone:
<PropertyGroup>
  <!-- Every run of the tool is a cold process, so nothing reaches the steady state
       tiered compilation is designed for. The library is untouched: a long-lived host
       keeps tiering, and DOTNET_TieredCompilation=1 overrides this. -->
  <TieredCompilation>false</TieredCompilation>
</PropertyGroup>
ReadyToRun, which is the usual answer here, measured worse on both cold and warm runs: its precompiled code targets a conservative instruction set, and this is SIMD-bound work that has to tier up regardless.
Rule 3: best of N, report the spread, and interleave the A/B
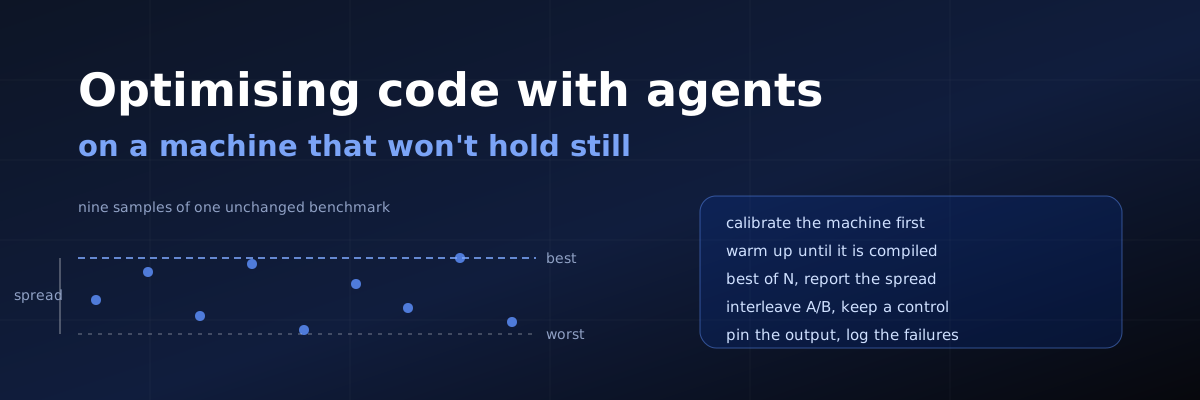
Best-of-N is the easy half. The best sample is the one least contaminated by whatever else the host was doing, and on shared hardware the noise is one-sided, so the best sample is also the least biased estimator available. Three is the floor; the GEMM sweep uses nine, because each sample is cheap.
The half that actually matters is reporting the spread beside the number. Here is the shape we use everywhere:
// Best of nine, and the spread reported beside it. On a shared host a single sample
// moves by 20% between runs, which is wider than most of the differences worth acting
// on; the best sample is the one least contaminated by whatever else the host was
// doing, and the spread says whether to believe the comparison at all.
const int Samples = 9;
double best = double.MaxValue, worst = 0;

for (int sample = 0; sample < Samples; sample++)
{
    var clock = Stopwatch.StartNew();
    for (int i = 0; i < repeats; i++)
    {
        Gemm.Linear(x, shape.Rows, shape.Inner, weight, default, y, shape.Cols);
    }

    double seconds = clock.Elapsed.TotalSeconds / repeats;
    best  = Math.Min(best, seconds);
    worst = Math.Max(worst, seconds);
}

return (best * 1000, flops / best / 1e9, worst > 0 ? (worst - best) / worst : 0);
On our reference machine that spread runs from 10% to 40%. That is wider than most differences worth acting on, which makes it the most useful number in this post: if you have not measured your spread, you do not know whether your 12% win exists.
Which leads to the rule that catches the largest class of false results:
Interleave the configurations
An A/B where all the A runs happen before all the B runs is not an A/B. Page cache, thermal state, and whatever the neighbouring tenant is doing all drift over the sequence, and the drift is attributed to whichever change you made. Run A, B, A, B, and bracket the whole thing with an untouched stage as a control.
The control stage is the cheap part and it is what makes a result publishable. When we widened the vision tower's attention to 512 bits, the claim was not "the page got faster". It was "vision went 200.6 s → 160.0 s with layout, prefill and decode flat and the markdown byte-identical". If the untouched stages had also moved, the machine moved, and the run says nothing.
For work where the effect is small enough that best-of-N and eyeballing the spread will not resolve it, we move to BenchmarkDotNet. It handles the multi-process isolation, the outlier detection and the statistical testing properly, and it measures allocation per operation along the way, which is usually the number we actually wanted. The date/time engine in Catalyst is a case where the differences were large but the allocation claim needed to be exact:
| Input | Microsoft.Recognizers | Catalyst | Faster | MS allocated | Catalyst allocated |
|---|---|---|---|---|---|
| Prose, 241 chars, no date in it | 972 µs | 138 µs | 7x | 52 KB | 0 B |
| Short sentence, one date | 482 µs | 15 µs | 32x | 70 KB | 472 B |
| Sentence dense in date expressions | 2,782 µs | 45 µs | 62x | 290 KB | 3 KB |
| Document, ~9.5 KB, 240 hits | 636 ms | 5.2 ms | 122x | 43.5 MB | 105 KB |
The rule of thumb we give agents: BenchmarkDotNet for anything under ~20% or anything per-call; a hand-rolled best-of-N harness for whole-stage and whole-document work, where a BenchmarkDotNet run would take an hour and the effects are large enough to survive it.
Rule 4: pin the invariant, not just the number
A performance claim that does not also assert correctness is worth nothing, because the fastest implementation of any function is the one that returns the wrong answer. This is more important with agents than without, because an agent optimising under pressure will absolutely delete a bounds check that was load-bearing and report the win.
So every optimisation in these ports carries an output assertion alongside the timing. In the OCR port that is byte-identical markdown across the test corpus. The six changes that closed the layout gap were accepted on "2.69 s from 3.8 s, and the output is byte-identical to the pre-optimisation build on all four test pages". In the embedding library, where the kernels are quantised and bit-identity is not available, every attention kernel was gated on a cosine check against the reference path: fp32 stays at 1.0, Int8 at ≈0.998, inside the quantisation tolerance. That check is what makes a "faster" kernel admissible at all. The two kernels that were ultimately rejected were rejected on measurement rather than on accuracy: quantising the value matmul as well as the scores is a convincing memory argument that measured slower, because the block-flash kernel already keeps each value chunk cache-resident and the convert costs more than the traffic it saves.
For allocation claims, assert on shape rather than on bytes, in a normal unit test:
private static long Measure(Action action, int iterations)
{
    for (int i = 0; i < 50; i++) action();     // JIT and lazy init out of the way

    GC.Collect();
    GC.WaitForPendingFinalizers();
    GC.Collect();

    long before = GC.GetAllocatedBytesForCurrentThread();
    for (int i = 0; i < iterations; i++) action();
    return (GC.GetAllocatedBytesForCurrentThread() - before) / iterations;
}

[Fact]
public void ScanningProseThatHoldsNoDateAllocatesOnlyTheEmptyResultList()
{
    long perCall = Measure(() => model.Parse(Prose.AsSpan(), Now, results), iterations: 2000);
    Assert.True(perCall == 0, $"expected an allocation-free scan, measured {perCall} bytes");
}
GC.GetAllocatedBytesForCurrentThread is exact and machine-independent, so "this scan allocates
zero bytes" is a claim that holds on any CPU, on a busy host, in CI. It is the one performance
assertion we are happy to put in a test suite and gate merges on.
What the discipline actually found
The rules are worth their overhead only if they change verdicts. They did, in both directions.
In the OCR port, once the layout graph's profile could be believed, it turned out to be wrong about itself three times in a row. First the mask head's element-wise kernels looked like the cost; vectorising them helped a little and moved the bottleneck. Then the graph turned out to be allocation-bound, at 4,458 MiB per detection, and pooling its intermediates took it from 7.5 s to 4.7 s where the arithmetic work had been worth nothing. Then the convolutions became 60% of it. Each fix moved the bottleneck somewhere the previous profile could not see, which is why the repository's own guidance now says, in bold: re-profile after every change to this graph rather than working down a stale list.
The vision tower went 40.8 s → 25.1 s on four changes that a naive harness would have scored as one win and three no-ops, because the first of them (capping the degree of parallelism, which was letting the thread pool inject workers into non-blocking work until the thread-time sum was 6.8x the wall time on a four-core box) was masking the other three.
The worst page in our corpus went 468.8 s → 240.1 s across six changes, none of which was a better inner loop. The largest were a pixel budget on page rasterisation and decoding a page's blocks as one batch, because a decode step re-reads 646 MB of weights whether it produces one token or forty. And separately, the most embarrassing finding of the whole exercise: upstream renders PDF pages at 144 dpi where we had defaulted to 200, so on every PDF in the comparison we had been doing 1.93x the work and being timed against it anyway. Those are the kind of findings a calibrated harness surfaces and a stopwatch does not.
In X-Ray.Content, the whole comparison is against a Rust original, so the harness runs both sides inside a single script (same fixture walk, same warm-up count, same output columns, one process tree) and prints the machine it ran on at the top. It compares only files both sides extracted, because a file one side refuses and the other parses is a correctness difference, and averaging it into a ratio quietly rewards whichever side did less work. Per-file ratios are reported as a median and a geomean with p10/p90, not as a single total.
And the negative results are the part we are most glad we kept. The OCR port has a whole section
titled Things that looked like wins and were not, nineteen entries, each with the argument for
it still intact, because the argument is convincing on paper and someone will otherwise try it
again. Interleaving the weight panel. Banding the GEMM over activation rows. Skipping im2col for
1x1 convolutions. Moving the KV cache off ArrayPool<T>.Shared (which was based on a stale
comment claiming the shared pool caps buckets at 1 MiB, which is .NET Framework folklore; the
shared pool round-trips a 1 GiB array with zero allocation, and the created pool we swapped in
churned 66 MiB per block). An agent that writes down its failed experiments is an agent that stops re-running them.
Memory is a different axis, and it needs different tools
Time is the number everyone asks for. Allocation is often the number that explains it: the layout graph above was allocation-bound while every timing profile pointed at arithmetic. It is also far easier to measure reliably, because allocation counts do not care how busy the host is.
GC.GetTotalAllocatedBytes gets you the total. What it will not tell you is which types and
from where, and the standard answers, dotnet-gcdump and dotnet-trace, are command-line tools
you point at a PID. That is fine at a desk and awkward everywhere else: inside a test, inside CI,
or inside a container where an agent has a shell but no interactive session and no tooling
installed.
So we built Memory.Introspect, a small MIT library that does what those tools do, from inside your own process.
dotnet add package Memory.Introspect
It wraps the official dotnet-gcdump, dotnet-dump and dotnet-trace logic (the EventPipe
plumbing is adapted from the .NET Diagnostics repositories) behind a typed API, so a capture is a
method call returning a result object rather than a subprocess returning text to parse.
What it captures. A .gcdump memory graph, a process .dmp, an EventPipe .nettrace, a
CPU-sampling profile, and the one we reach for most, an allocation report by type:
var introspector = MemoryIntrospector.Create(new() { Logger = logger });

var report = await introspector.CollectAllocationReportAsync(
    Environment.ProcessId, TimeSpan.FromSeconds(10), count: 10);

AllocationTracing.Write(Console.Out, report);
Top 3 Allocated Types of 3 (16.66 GiB total, 167,438 AllocationTick events)
Type                                                        Bytes        %          LOH    Objects
1. System.Byte[]                                         16.65 GiB   99.99%           -          -
2. System.InvalidOperationException                       1.73 MiB    0.01%           -          -
3. System.GCMemoryInfoData                              104.29 KiB       0%           -          -
The LOH column is the one that pays for itself. A type showing bytes there is allocating past the 85,000-byte threshold, which is a different and usually worse problem than the same byte count spread across small objects.
Where it came from. EventPipe already records a call stack for every allocation event; what it cannot do without rundown is give you the method names to resolve them against. So asking for stacks turns rundown on:
var report = await introspector.CollectAllocationReportAsync(
    pid, TimeSpan.FromSeconds(10), count: 10, outputPath: null, resolveCallStacks: true);

AllocationTracing.WriteCallStacks(Console.Out, report);
Top 3 Allocating Call Stacks

1. 44.35 GiB (100%)  System.Byte[]
      Workload.AllocateGarbage(CancellationToken)
   <- Workload+<>c__DisplayClass0_0.<RunAsync>b__3()
   <- ExecutionContext.RunFromThreadPoolDispatchLoop(...)
   <- Task.ExecuteWithThreadLocal(...)
   <- ThreadPoolWorkQueue.Dispatch()
It is opt-in because it costs at both ends: rundown makes stopping the session slower and the
trace larger, and resolving stacks needs TraceLog, which converts the trace to ETLX first. Keep
the durations short.
The property that matters for agents is that every capture works against the current
process. Pass Environment.ProcessId and the library connects to its own diagnostics endpoint,
which means a capture is something a test can do to itself:
[Fact]
public async Task CheckoutDoesNotAllocateLargeBuffers()
{
    var introspector = MemoryIntrospector.Create();
    using var cts = new CancellationTokenSource();
    var workload = Task.Run(() => RunCheckoutLoopAsync(cts.Token));

    var report = await introspector.CollectAllocationReportAsync(
        Environment.ProcessId, TimeSpan.FromSeconds(5), count: 25);

    cts.Cancel();

    long loh = report.Types.Sum(t => t.LargeObjectHeapBytes);
    Assert.True(loh < 10 * 1024 * 1024,
        $"LOH allocations regressed to {loh:N0} bytes:\n{Render(report)}");
}
Two things make a test like that survive contact with CI, and they are the same two rules as above wearing different clothes. Assert on shape, not on exact numbers. "No type over N MB", "this type is not in the top five" hold across machines where byte counts do not. And always render the full report into the failure message, because a red build with a number and no context tells nobody anything, and an agent handed that failure will guess.
The numbers come from GCAllocationTick, which the runtime emits once per ~100 KB allocated. So
allocated bytes per type are accurate and per-object counts are not available; give the workload
enough to do before you believe a total.
It ships its own agent documentation. The package carries a Claude skill in its skills/
folder, and a buildTransitive target extracts it into .claude/skills/memory-introspect/ of
any consuming project that has a .claude folder at or above it: one SKILL.md plus twenty
reference pages covering each capture type, its options and its failure modes. No .claude
folder means the target does nothing. That mechanism is its own
post; the point here is that an agent that picks up this
library also picks up the knowledge of how to drive it, which removes one of the most common
reasons agents avoid a diagnostic tool: they do not know it exists.
Where this lives: a skill and a CLAUDE.md section
Both, and the split between them turned out to be the useful part.
The method is a skill. .claude/skills/measuring-performance
in the OCR port is everything above, written for the agent rather than for a reader: nine sections
covering calibration, compiled code, best-of-N with the spread, interleaving against a control,
finding what a stage is bound by, the microbenchmark traps, pinning the output, measuring
allocation, and writing down failures. It ends with a checklist a result has to satisfy before it
is quoted:
- [ ] The machine was calibrated in the same run, and the jitter is stated.
- [ ] The code under test was warm, or deliberately measured cold, and it is said which.
- [ ] Best of at least three, with the spread reported beside the figure.
- [ ] The configurations were interleaved, both endpoints repeated.
- [ ] An untouched stage is quoted beside the changed one as a control.
- [ ] The output is byte-identical, or the tolerance is stated and pinned by a test.
- [ ] Allocation was checked as well as time.
- [ ] If the change was rejected, it is written down in CLAUDE.md with its measurement.
The measurements are a CLAUDE.md section, and they have to be: they are what this repository
has already learned, and a skill that loads on demand is the wrong place for something an agent
needs before it knows it should be careful.
CLAUDE.md keeps roughly 850 lines of record:
- Where the time goes covers the stage breakdowns, what each profile reports, and why a page's cost is not the sum of its blocks.
- Where the allocations go keeps the three times the file was confidently wrong about its own bottleneck, with the instruction to re-profile rather than work down a stale list.
- Things that looked like wins and were not is the nineteen dead ends, each with the argument for it intact.
The rule we ended up with is that a skill says how to measure, and CLAUDE.md says what has
already been measured. The skill still quotes this project's numbers as its worked examples,
which is deliberate: an abstract rule about interleaving is forgettable, and the same rule with
the background-GC run that fooled us attached to it is not. But every rule in it holds with those
examples removed, which is the test of whether it belonged in a skill at all.
Memory.Introspect ships
a skill in its package
for the same reason: "how do I capture an allocation report" is a question with the same answer
in every repository, so it travels with the tool.
The prompt, roughly
None of this is exotic, and it fits in that same instructions file. What we ask for, near verbatim:
Calibrate before you measure
Measure this machine's FMA rate and memory bandwidth before loading anything, and report every stage as a fraction of those ceilings as well as in milliseconds. Print the jitter.
Warm up, and say how
Untimed passes until the numbers stop moving. If the production path is a cold process, say so and measure it cold.
Best of three, spread reported
Never report a single sample. Report the best and the spread beside it. If the spread is wider than the effect, the effect is not established.
Interleave the A/B, keep a control
A-B-A-B, never A-A-B-B. Bracket with an untouched stage; if the control moved, the machine moved and the run says nothing.
Pin the output
Every optimisation carries an output assertion: byte-identical output, or a stated tolerance. A win without one does not land.
Write down the failures
Every rejected experiment goes in the notes with the argument for it intact, so the next session does not run it again.
The last one is the one people skip and the one that compounds. Agent sessions do not share memory; the repository is the memory. An optimisation section that records only the wins is a section that will re-derive the same nineteen dead ends every few months, each time at the cost of a full measurement cycle on a machine that is lying to it.
What we would say to someone starting
The instinct when a benchmark is noisy is to run it more times. That helps with random noise and does nothing about the two things that actually corrupt these measurements: systematic drift across a sequence (which interleaving fixes and repetition does not), and being bound by something other than the thing you are changing (which only a calibration and a control will reveal).
The part that surprised us is which code turned out to matter. Not the kernels: the measurement harness. Four hundred lines of machine profiler and a best-of-nine loop are what made it possible to hand an agent "make this faster" and get back something we could believe, across a 1.93x end-to-end win over the original Python pipeline, a 12x on a page where the decoder had been falling into a repetition loop, and nineteen documented failures nobody has to try again.
Build the harness first. The agent is good at the rest.
The code in this post is from four open repositories:
PaddleOCR-VL in C# (MachineProfile,
GemmBenchmark), X-Ray.Content (the Rust-vs-C#
extraction harness), Catalyst (allocation tests, the
BenchmarkDotNet comparison) and
sentence-transformers-sharp
(kernel sweeps gated on cosine checks). The machine-profile block is a sample of the output
format rather than a published measurement; every figure quoted in prose is measured and recorded
in the repository it came from. Memory.Introspect is on
NuGet and
GitHub, MIT licensed.
Read next
Articles on context graphs, enterprise search and industrial AI